I'm a B.Tech student at IIT Roorkee and a core member of the Data Science Group. I work on multimodal generative modeling — efficient diffusion distillation, and the measurement, mechanisms and mitigation of hallucination in vision-language models.
Interested in model internals and how pipelines work. Reasoning about the WHY is my philosophical attitude towards AI
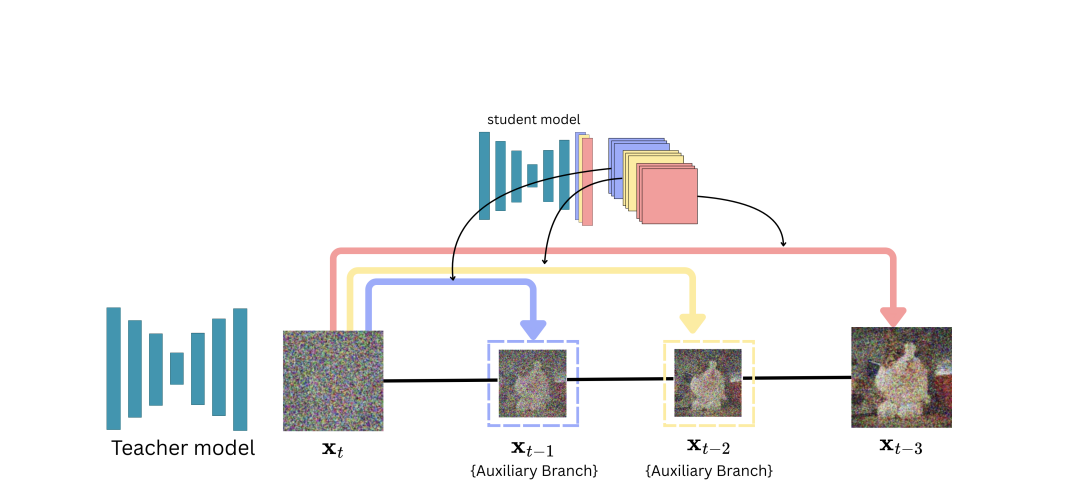
Supervise a distilled diffusion student on the teacher's full denoising trajectory, recovering the intermediate steps that standard distillation throws away.
The student gets K-fold branched output channels (K·C instead of C), so each branch is supervised against a different point on the teacher's trajectory. The gains above cost roughly 0.01% extra FLOPs during training, with identical inference cost.
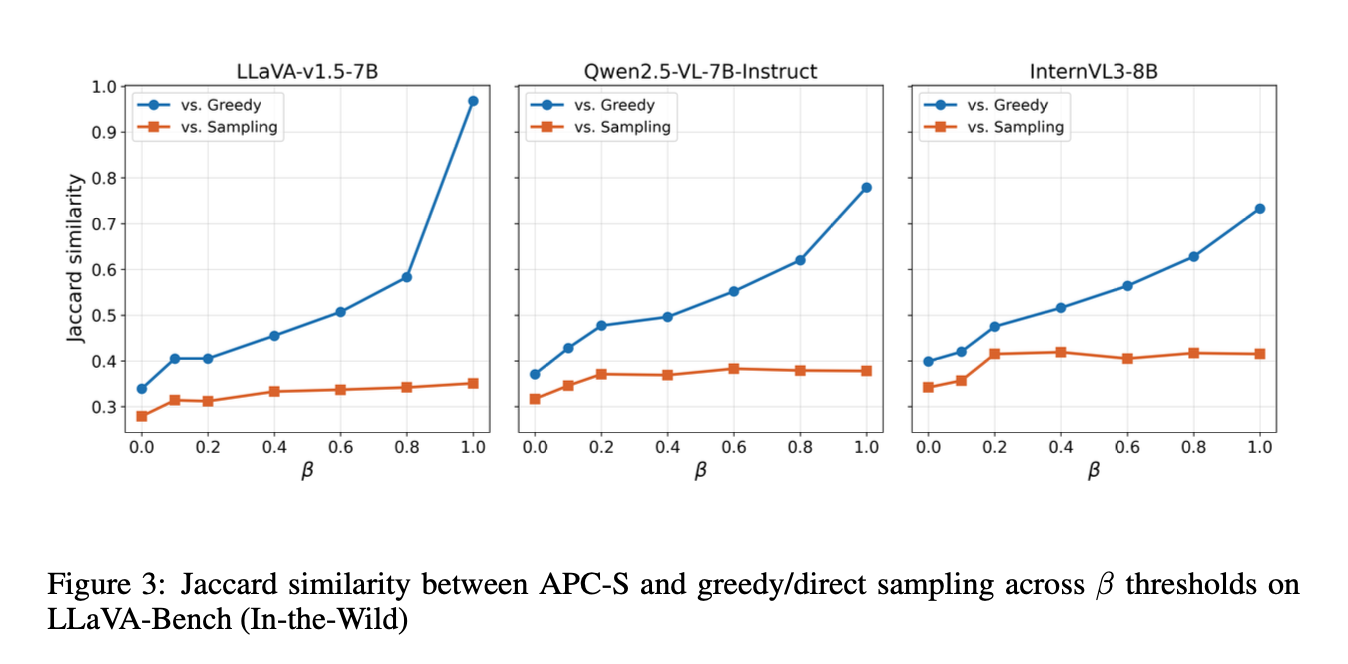
A reproducibility study stress-testing VCD, ICD and SID across LLaVA-1.5 (7B / 13B) and Qwen2.5-VL on POPE, MME and CHAIR, against spurious, non-visual controls. A logit-lens analysis localizes the layers where the intervention breaks down.
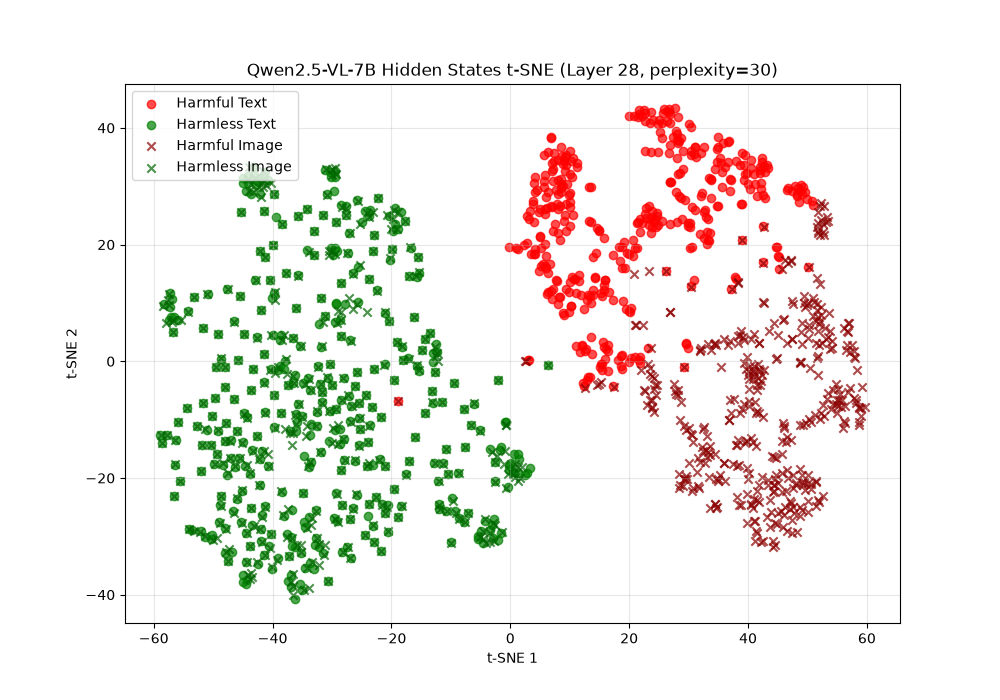
Do safety-tuned VLMs share one refusal direction across text and images, or carry a separate, weaker one for images? Adapter-style LLaVA-1.5-7B keeps the two apart; natively multimodal Qwen2.5-VL-7B merges them by two-thirds depth.
Per-layer refusal directions are class-mean differences of last-token residual states on AdvBench vs. Alpaca, with every prompt also rendered as an image. They are measured against bootstrap CIs, split-half noise ceilings and a random-direction null, then tested causally with Arditi-style cross-modal steering and directional ablation.
In LLaVA the image direction is 2–9× weaker and never induces refusal; in Qwen, image refusal runs through the text direction after a sharp layer 13 → 14 transition. On natural images (VLSU), harm reaches the final token as clearly as CLIP sees it (AUROC 0.95) but moves at most 8% (LLaVA) / 16% (Qwen) of the way along v_text: seen, partly aligned, too weak to trigger refusal. Style-matched probe controls rule out length and phrasing, but not word content, so the typographic results may partly reflect OCR.
PyTorch · HuggingFace · linear probes · activation steering
A resumable pipeline that turns raw ChartQA samples into a fine-tuning corpus of structured visual chain-of-thought traces — summary → extraction → computation → answer.
Three traces per item are sampled from a frontier VLM teacher and filtered through schema, answer-correctness, numeric-grounding, arithmetic re-verification and 2-of-3 self-consistency gates; the most grounded survivor is kept.
Python · agentic workflow · VLM API
Education & Service
IITR
Indian Institute of Technology Roorkee
B.Tech, Energy Engineering
2024 – 2028
DSG
Data Science Group, IIT Roorkee
Core member · research on multimodal generative models